

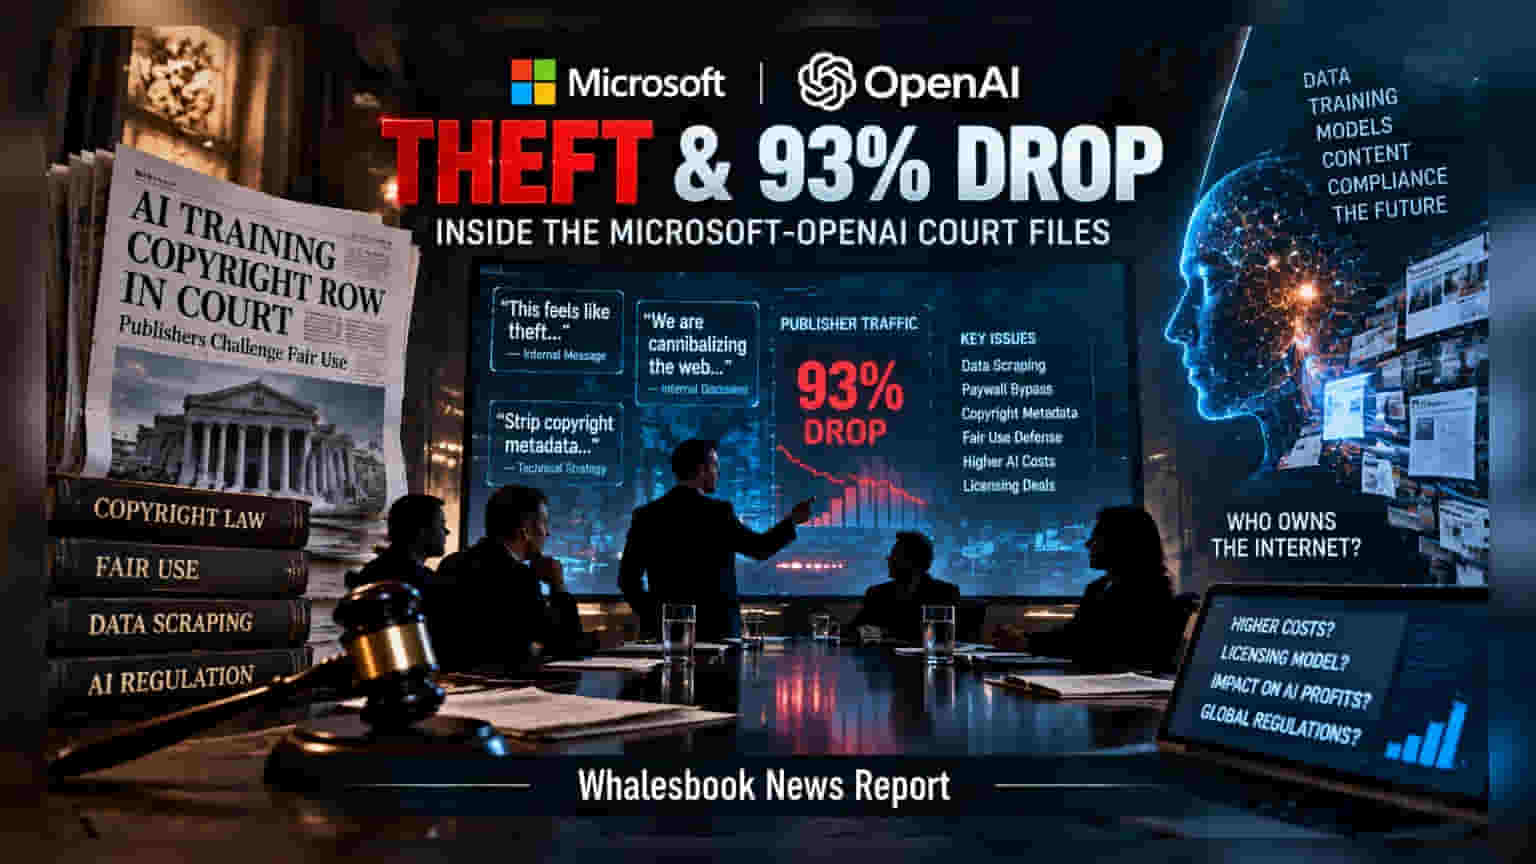
Newly released court filings show Microsoft and OpenAI leaders internally raised concerns about the ethical and legal risks of their AI training methods. The documents suggest that AI models reduce traffic for publishers, which could weaken their legal 'fair use' defense. For investors, this adds regulatory and financial pressure on AI firms to potentially pay for training data.
A legal battle in the United States involving Microsoft and OpenAI has reached a new stage after internal court filings were unsealed. The documents reveal that leaders at both companies privately debated the ethics and potential legal implications of how their Artificial Intelligence models were trained, with some internal communications characterizing the data scraping methods as a form of theft.
Impact on Business Models and Publisher Traffic
At the heart of the controversy is a challenge to the companies' fair-use defense. The filings detail internal concerns that AI training methods, specifically the integration of AI-driven answer engines like Microsoft Copilot, directly cannibalize traffic from original content creators. One presentation noted a 93% decline in referral traffic for publishers such as The New York Times when Copilot was used in search queries. Microsoft employees described this dynamic as a doom loop, where the AI systems depend on the web for information but simultaneously degrade the health of the very websites they scrape to function.
Technical and Ethical Challenges
The court filings also contain evidence regarding technical strategies used to prioritize data volume over copyright compliance. Documents indicate discussions among OpenAI employees about methods to bypass paywalls. Additionally, the filings suggest that there was a deliberate strategy to strip copyright metadata from training datasets, which could prevent the AI models from inadvertently outputting restricted information. These technical practices complicate the legal argument that the companies were merely using publicly available information for transformative purposes, which is a key pillar of the fair-use defense in copyright law.
Why This Matters for Investors
For investors in the technology and AI space, this litigation sets a significant legal precedent. If courts rule that AI companies must pay for the data used to train their models, the cost structure for AI development could rise sharply. Companies that rely heavily on massive datasets might face higher operational expenses, potentially shifting toward licensing deals rather than free scraping.
In India, where IT companies are rapidly integrating AI solutions and building indigenous models, these global developments highlight the growing importance of intellectual property compliance. Investors may want to monitor how this legal dispute concludes, as it could influence global regulations on AI data training. The key monitorable will be whether companies move toward formal content licensing agreements, which could impact profit margins but provide greater regulatory clarity for the long-term sustainability of AI businesses.